preloop debug, run shell commands in the guest, synchronize a fix, and retry the failed step or an earlier step. Use --preserve-on-failure instead when you need a post-mortem shell without pausing the worker for a verdict.

Choose how a failure is held
--debug and --preserve-on-failure are alternative failure modes. A plain run on the default backend keeps its terminal behavior for compatibility; explicit flags make scripts and agents unambiguous.
Attach to a paused job
Runpreloop debug without a reference when exactly one session is paused:
--json prints the paused session projection for scripts. The failure banner includes the step command, exit code, workflow position, working directory, structured diagnostics, and a short log excerpt. The job and microVM remain paused while you inspect them.
Anything entered without a leading colon runs as a non-login sh -c command in the failed job’s workspace:
Control the session
At thepreloop debug prompt, colon-prefixed commands control the session. Other input goes to the guest shell.
The CLI exposes the same non-interactive decisions:
--revert accepts none, untracked, or all. A retry restores runner-managed state such as step outcomes and file-command contexts. It does not undo external API calls, processes outside the workspace, or other external side effects. A step accepts at most 25 attempts.
Preserve a VM for a shell
Use this path when a completed failure is easier to diagnose from a normal shell than from a paused step:preloop shell finds it automatically. If several VMs are held, use the name printed by the error:
DAP debugging
The DAP flow is useful when an agent or editor needs structured scopes and stack frames. Enable it on the run submission with the native API:configurationDone. The default connection window is 15 minutes; ACTIONS_RUNNER_DAP_CONNECTION_TIMEOUT changes that value in minutes. The built-in client supports:
github, env, runner, job, steps, and secrets scopes. Secret values are masked. next, stepIn, and stepOut resume like continue; execution stops at job step boundaries rather than inside a shell command. The client can inspect the final state after job completion before the DAP transport closes.
preloop dap RUN_ID accepts --url URL and --token TOKEN. The endpoint is standard DAP over a WebSocket route, so a DAP-capable editor such as VS Code can use the same run endpoint with a WebSocket-capable adapter. The recorded omp workflow uses the small dapctl reference client; the same sequence is shown below.
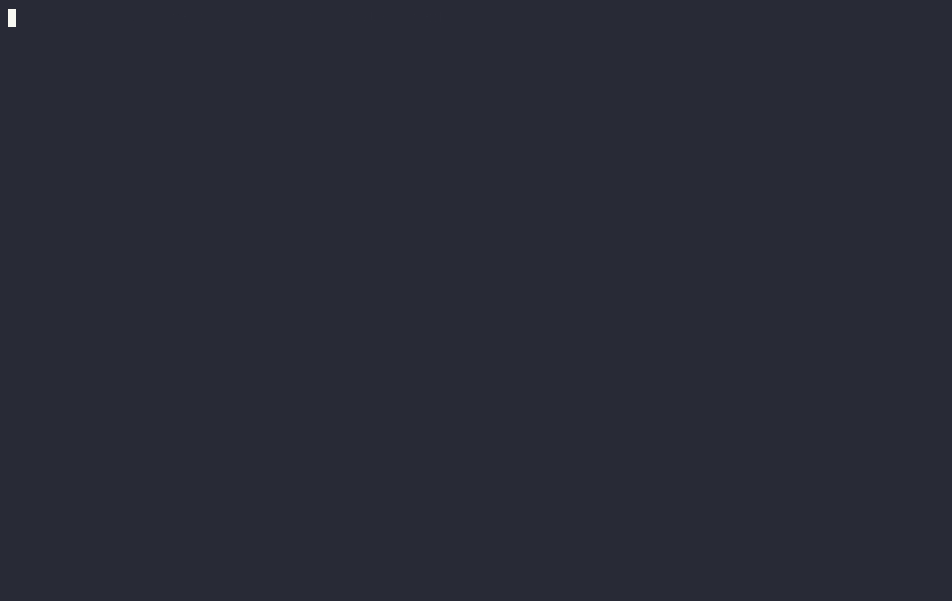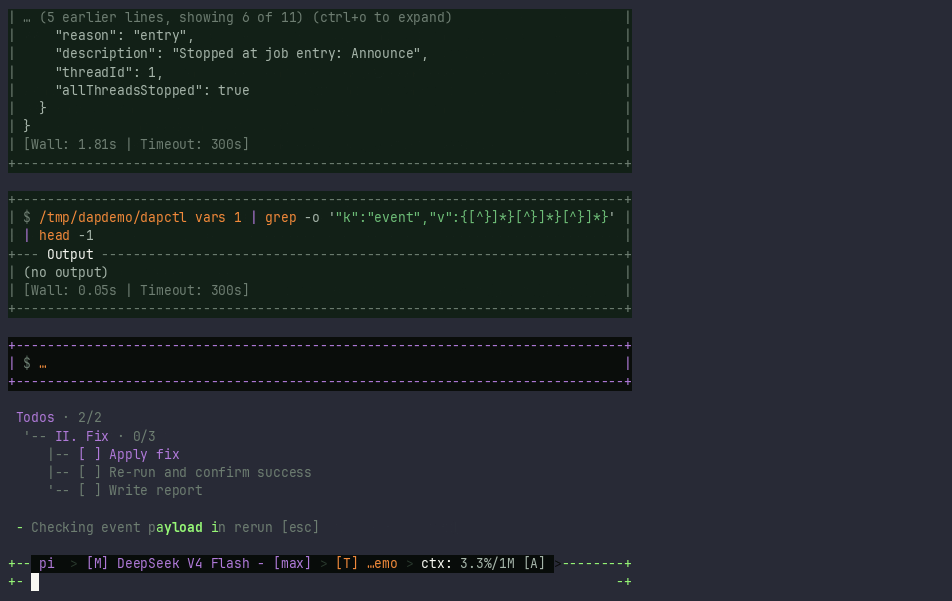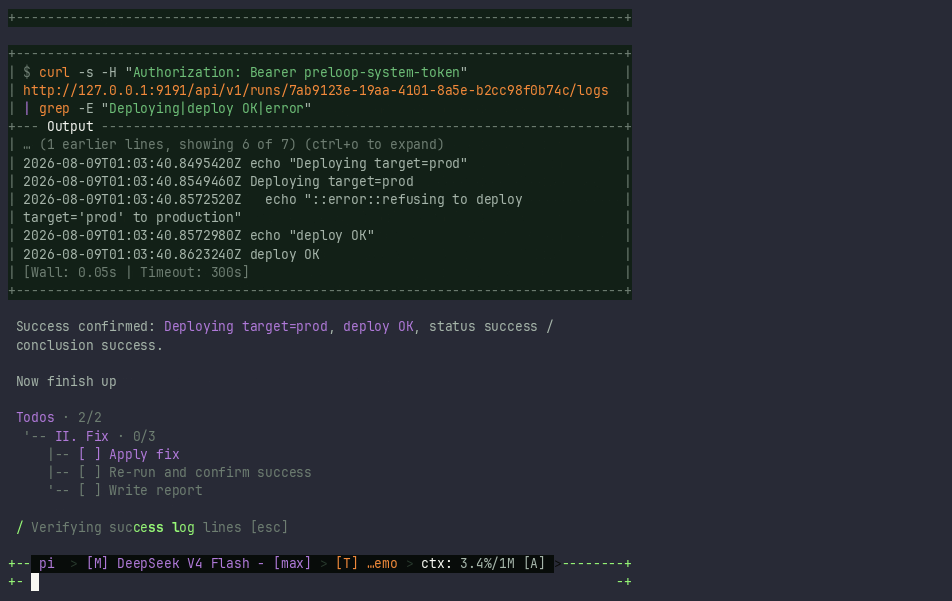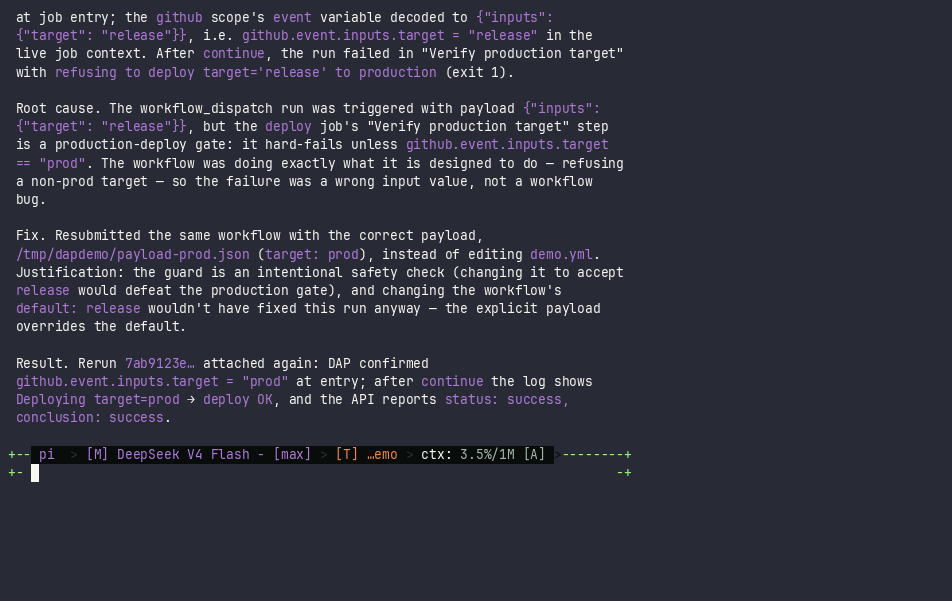
github.event.inputs.target in the github scope, identifies the wrong deployment input, and submits the corrected payload. It is a demonstration of the DAP inspection loop; use your own workflow and credentials for a real run.
Full DAP session recording
Full DAP session recording
The complete recording shows the agent’s whole session, from attaching to the paused run through the corrected rerun.The same recording is available as an animated GIF and as asciinema casts (
docs/demo/dap/demo.cast, docs/demo/dap/demo-highlight.cast) in the repository.